I was right about my AI coding bill for the wrong reason
Earlier this month I posted that most of my Claude Code bill wasn’t paying for code. Over 90% of the spend went to re-sending conversation history. Then I set out to build two habits: clear every session in the evening, and keep each task’s context in a Markdown file so a fresh session can pick it up. I believed the model was capping my sessions at around 160k tokens. A cost analysis Claude ran on my transcripts said my daily spend had dropped by about two-thirds, and I believed I was delivering more.
That’s what I would have told you. Then I checked it against the bill. The number held up. Almost nothing behind it did.
What I believed vs what the bill shows
Same person, three periods. Spend comes from my cloud billing, by day and model. Session sizes and call-level detail come from Claude Code’s own transcripts, because billing can’t see either. My first estimate from the transcripts undercounted the older weeks, which is why spend here comes from the bill. I leave out 26 September, the day I switched models, because it mixes both.
| I believed | The data shows | |
|---|---|---|
| Spend vs Opus 4.7 | Down two-thirds, thanks to my habits | Down two-thirds, but not from my habits |
| 160k session cap | Set by the model | A Claude Code default, until 2 October |
| Evening clear | A habit I was building | Didn’t happen: 11 of 12 mornings |
| Delivering more | Yes | No measure I have shows it |
So my number was right and my reason was wrong. Spend fell to about a sixth before 3 October, while a Claude Code default capped my sessions, then doubled after an update on 2 October moved that cap to about a million tokens. Eleven of twelve mornings started in yesterday’s session. The Markdown file per task I can’t measure either way.
Spend fell to a sixth before 3 October, then doubled after.


The cap wasn’t the model’s
The cheap week was cheap because Claude Code compacted my sessions at about 167k tokens, several times a day. I thought the model was doing that. It was Claude Code’s default at the time, and nothing in my config set a limit until 15 October, when I went to check.
Then the default moved. On Opus 4.7 my sessions already ran to a million tokens. When I moved to newer models in late September, Claude Code capped them at 200k, even though the model itself accepted a million. Claude Code 2.1.287, released 1 October, made a 1M window the default for the newer models on Vertex and the other cloud providers too. My setup picked it up on 2 October. The compaction point moved with the window, from about 167k to nearly a million, and my sessions grew past 800k.
From 2 October my sessions stopped stopping at 167k.


The clear I didn’t do
On 11 of 12 mornings, my first call of the day landed in a session from an earlier day, carrying a median third of a million tokens of yesterday. I meant to clear. I usually didn’t. Those two weeks were a production incident and a big piece of work I can’t say more about, and at the end of most days I was mid-task. Then the kids come home from barnehage and the rest of family life takes over, and the session is still there in the morning, carrying yesterday.
Why size is the whole story
The price of one call scales with how much context it carries. In my logs, a call at 500–600k tokens costs three to four times what a call at 100–200k does. Between the cheap week and after, the price at a given size barely moved. What moved was how many calls ran big: none above 300k in the cheap week, one in six above 500k after. That explains the rise after 3 October. Why spend is still a third of the Opus 4.7 level, I can’t fully explain yet.
And the expensive moment is the pause. Since 3 October, about 90% of what I paid to rebuild the cache came on calls after a gap of five minutes or more, which is how long the cache lives.
What I believed about delivery
I believed I was delivering more. The logs can’t show it. Since 3 October, output tokens are down, file edits and shell commands are flat, fewer repos get touched, and commits in work repos are too noisy to read either way. Those can’t see task size, work outside Claude Code, or quality, so this doesn’t prove I delivered less. It means “more” was a feeling.
Quality is a bit better. My PRs get fewer review comments, and peers accept my Slack messages without back-and-forth. One thing helps: I tag text for humans and text for machines separately, in PR descriptions and on Slack, so people skip the machine part and read less. But I switched models in the same window, so some of this could be the models, not me.
Why I didn’t notice
I didn’t notice because the number I had was right. Two-thirds down against the old model is true, so I had no reason to look closer. But the drop came the week before I started on the habits, and when spend doubled after 3 October, my status line couldn’t show it. The dollar figure is the part of my status line I watch most, but it’s the cost of one session, not one day, and a session that never ends never gives me a day’s total. I watched the meter and missed the bill.
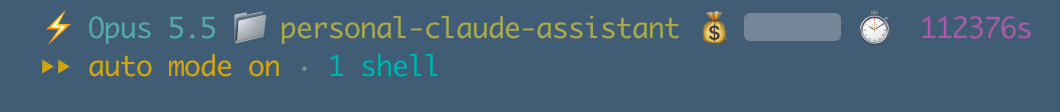
If I could have the right number for the wrong reason, with a status line on screen and a cost analysis two weeks old, I’d bet most engineers know roughly what they spend and not why.
What I’d tell anyone using a coding agent
- Pin the defaults that drive cost, like the auto-compact point, in your global config from day one, and re-measure after every tool or model update. Updates are when defaults move, and I only found mine when I went looking.
- Make the day’s spend visible, not just the session’s. My status line shows session cost, and a session that never ends never shows you a day. This week it showed a 31-hour session, which should have been my first hint.
- Your sense of the spend can be right and still tell you nothing about why. Check the cause against the bill, not only your local logs. Mine undercounted.
What I’d tell a tech lead
- Org-level usage dashboards are infrastructure work. Don’t wait for them. A billing export, broken down by day and model, gets you most of the way today.
- Write down which defaults drive cost and check them after every update, as a team, not one engineer at a time.
What’s next
Instead of trusting myself to clear every evening, I’ve set auto-compact to 250k globally and for every subagent. I’ll measure the next two weeks, 16 to 29 October, and publish the real “after” in early November, including whether a fixed compaction point does what my evening clear didn’t.
If you run coding agents across a team: how do you find out a default changed before the bill tells you?